 Cloud & Business Apps
 Cybersecurity
 Data & AI
 IoT & Connectivity
 Industry
 Health
 Banking and Finance
 Public Sector
 Retail
 Tourism and Leisure
 Transport & Logistics
 Energy & Utilities
 Smart Cities

Edge Computing and distributed AI: where to run each workload
- Introduction
- From centralised Cloud to a computing continuum
- Training and inference: different stages, different requirements
- When does it make sense to move AI to the Edge?
- Latency
- Data volume and network usage
- Continuity and resilience
- Data location and control
- Mobility
- From computer vision to AI agents: Edge AI applications
- Orchestrating distributed AI
- The challenges of distributed AI
- Conclusion
Introduction
Not all AI workloads require the same infrastructure. Training a large model, analysing images from an industrial camera or using Artificial Intelligence with corporate information all involve different requirements for processing, connectivity, latency and data management.
The Cloud and large data centres remain the right environment for many of these workloads, particularly when they require significant compute capacity. However, in sectors such as industry, retail, mobility and logistics, much of the data comes from cameras, sensors, machines or vehicles. Continuously sending that information to centralised infrastructure can increase the distance data travels across the network and delay responses that need to happen close to where the activity takes place. Some functions can also run directly on a local device, provided it has sufficient capacity.
In this scenario, Edge Computing occupies the space in between. It brings processing and storage capacity closer to where data is generated or used and makes it possible to run workloads there that do not need, or are not best suited, to being sent to the Cloud or a centralised data centre and which, due to capacity or other application requirements, are also not practical or possible to handle entirely on the local device.
■ Cloud, Edge and devices can therefore form a distributed architecture in which each part of the application runs where its requirements are best met. The decision is about determining the most appropriate location for each workload.
The key decision is to place each AI workload where its requirements for compute, latency, connectivity and data processing are best met.
From centralised Cloud to a computing continuum
When these layers work together in a coordinated way, the infrastructure operates as a computing continuum (Cloud Continuum). At one end are Cloud regions and large data centres; at the other are the devices that generate or consume information. In between, Edge adds processing and storage capacity closer to users, equipment and operations.
The right location depends on the application. A workload that prioritises compute capacity and scalability can run centrally. A workload that is latency-sensitive, continuously generates large volumes of data or needs to be processed close to where the data is generated can benefit from Edge. And some functions can run directly on the local device.
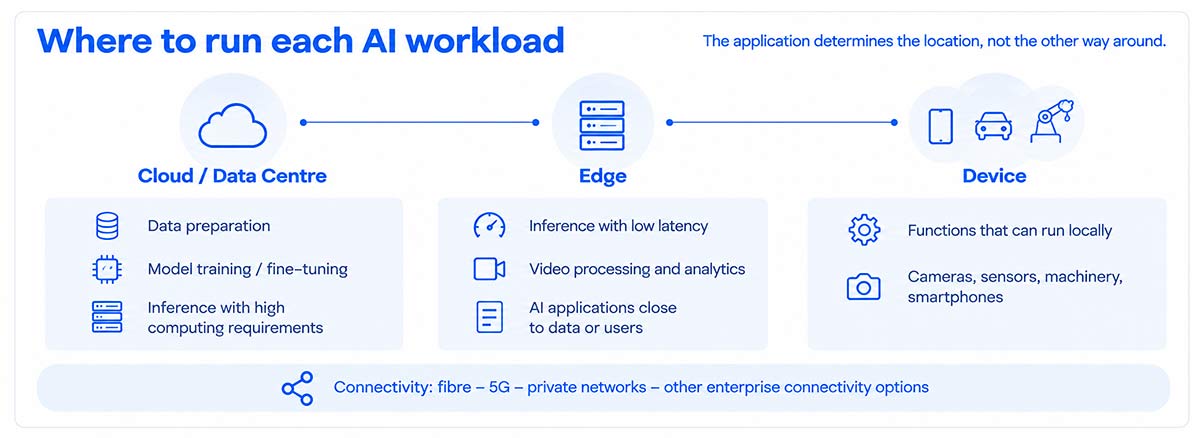
For these layers to operate as a distributed architecture, connectivity is essential. Fibre, 5G, private networks and other enterprise connectivity options link devices, Edge and Cloud, making it possible to combine resources located in different places. But connecting them is not enough: it is also necessary to manage and coordinate where applications run, rather than treating each node as isolated infrastructure.
■ In Spain, Telefónica has strengthened this layer with the deployment of 17 Edge nodes and associated B2B services across different production areas. Their integration with fixed and mobile networks makes it possible to run certain workloads closer to business operations when the use case requires it.
Training and inference: different stages, different requirements
The model lifecycle helps make this distribution more concrete. Preparing large datasets, training and certain fine-tuning processes require high compute capacity, so they are usually run on centralised, specialised infrastructure.
Inference, by contrast, can be distributed more flexibly. Once trained, the model uses new data to generate a prediction, classification, response or decision. Some inference workloads still require significant resources and run centrally; others can run at the Edge when proximity provides a specific advantage.
In simplified terms:
- Cloud and large data centres: data preparation, training and fine-tuning, as well as inference workloads that require significant compute capacity or do not have strict proximity requirements.
- Edge: certain inference workloads, computer vision, video processing, RAG and other applications that benefit from running close to the data or users.
- Device: AI applications capable of running certain functions directly on smartphones, cameras, vehicles, machinery or other equipment.
■ These categories do not create rigid boundaries. The same application can use multiple layers: training or updating a model on centralised infrastructure, running inference close to the operation and leaving the functions that can be handled locally to the device.
When does it make sense to move AI to the Edge?
Edge Computing adds value when proximity addresses a specific application requirement. There is no single criterion; several usually come into play.
Latency
Reducing the network distance between where data is generated and where it is processed can shorten response times. This is particularly important when an application must react within very tight timeframes, as in certain industrial, computer vision or mobility scenarios.
Data volume and network usage
Cameras, industrial sensors and other devices can generate large volumes of information continuously. If a decision can be made from an alert, classification or processed result, it is not always necessary to send all the data to more distant infrastructure.
Continuity and resilience
Keeping certain functions close to the operation can reduce dependence on remote resources. Edge, however, does not guarantee continuity on its own: the outcome depends on the design of the application, infrastructure and connectivity.
Data location and control
Some use cases need to control where certain information is processed or stored. Edge makes it possible to incorporate location into the architecture design. Proximity, however, does not automatically mean privacy, sovereignty or regulatory compliance; these requirements need additional measures.
Mobility
When users, vehicles or devices change location, the most appropriate node for running or serving the application may also change. Latency, location, connectivity, available resources, network capacity and data requirements can all influence that selection.
■ These factors often overlap. The design should identify which parts of the application are best suited to the Cloud, which benefit from Edge and which can run on the device.
Edge adds value when proximity changes how the application behaves: reducing latency, avoiding unnecessary data movement or keeping certain functions close to the operation.
From computer vision to AI agents: Edge AI applications
Use cases help illustrate this distribution. Computer vision is one of the clearest examples. In a factory, it can be used to detect defects or analyse production processes; in retail, for image recognition, loss prevention or other video-based applications. Industry and logistics also offer scenarios such as predictive maintenance, robotics, fleet optimisation and asset tracking.
Processing images close to where they are captured avoids having to send the entire video stream to remote infrastructure. The application can run inference there and then send an alert, a classification or only the information required by the rest of the system.
Rail transport provides one example of this architecture. Telefónica and CAF (in Spanish) have developed a pilot combining 5G SA, Network Slicing, Edge Computing and AI. The solution uses computer vision to analyse images captured inside trains and processes the information at the nearest Edge node, without the need to install a processing node in every carriage.
Generative AI is also expanding these scenarios. In applications based on Retrieval-Augmented Generation (RAG), inference and information retrieval can be located close to the corporate data used by the application. The same approach can be applied to certain agents and other solutions that combine AI models with enterprise information.
■ These capabilities are also becoming part of the Edge proposition for businesses. Telefónica's portfolio is built on Telefónica Tech Cloud Platform and includes GPU compute capacity and AI services using agents and RAG. This broadens the options for placing certain AI workloads closer to the data or the user when the use case requires it.
Orchestrating distributed AI
As the number of possible execution locations increases, another challenge emerges: having distributed resources is not enough. It is necessary to decide which ones to use and manage them as part of a single architecture.
Orchestration makes it possible to factor latency, location, connectivity, available resources, network capacity and data-related requirements into that decision.
At this point, Smart Edge helps select the appropriate node and instantiate applications across distributed infrastructure. This means that an application does not have to remain permanently tied to a single location.
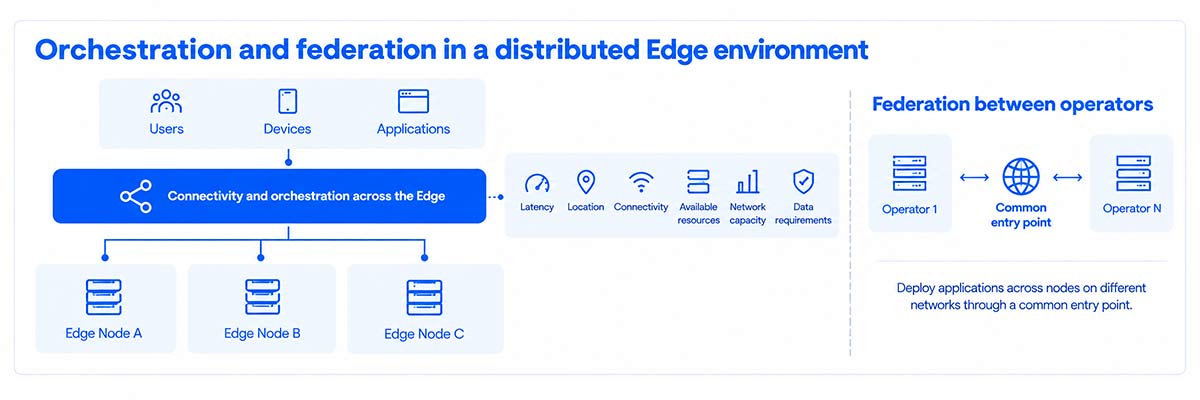
This capability is particularly relevant in mobility scenarios. If a user, vehicle or device changes position, the node offering the right conditions to deliver the service may also change. Management shifts from isolated nodes to coordinating the infrastructure as a whole.
■ Federation between Edge environments from different operators can extend this model, making it possible to deploy applications across nodes on different networks through a common entry point. It is therefore one of the building blocks of a Cloud-Edge Continuum in which applications and resources can be distributed across different layers and infrastructures.
The challenges of distributed AI
This flexibility comes with trade-offs. Bringing processing closer to users, devices and operations means working with infrastructure that does not always offer the same capacity as a large data centre.
Edge-node resources can be more limited, so models and applications need to be adapted to the available capacity. When necessary, techniques such as quantisation, pruning and knowledge distillation can reduce the requirements of certain models and make them easier to run in these environments.
Distribution also increases operational complexity. If an application runs in different locations, teams need to coordinate versions, updates, deployments, observability and monitoring across multiple environments to maintain consistent model management throughout the AI lifecycle.
Security is part of the same challenge. Processing certain data closer to its source can reduce some data movement, but a distributed architecture introduces more nodes, interfaces and components to manage and protect. Teams need to build security into AI applications from the outset and maintain consistent policies across the infrastructure.
■ That is why moving an AI workload to the Edge should address a specific need. Proximity adds value when it improves a variable that matters to the application; adding another infrastructure layer without that justification increases complexity without necessarily delivering an advantage.
Conclusion
The decision about where to process is becoming part of the design of AI applications themselves, as they become integrated into more and more processes.
Large data centres continue to play a central role in training and compute-intensive workloads. Devices can handle certain functions when they have sufficient capacity. Between the two, Edge brings processing closer when latency, data volume, mobility, continuity or data location make proximity beneficial.
The deployment of Edge infrastructure, its integration with communications networks and the addition of AI capabilities broaden the available options. Cloud, Edge and local devices do not need to be treated as mutually exclusive alternatives: they can form part of the same computing continuum.
The design should start with the application. Its requirements determine where processing should take place, what connectivity is needed, how the different resources should be coordinated and how the solution should be operated and protected throughout its lifecycle.
Cloud, Edge, connectivity and devices form a single distributed architecture; the value lies in coordinating where each part of the application should run.
Updated: 2026.09